Automatic word segmentation for Taiwanese: building a national corpus search system
National-Scale Language Data Engineering: Taiwanese NLP and Corpus Search System Development
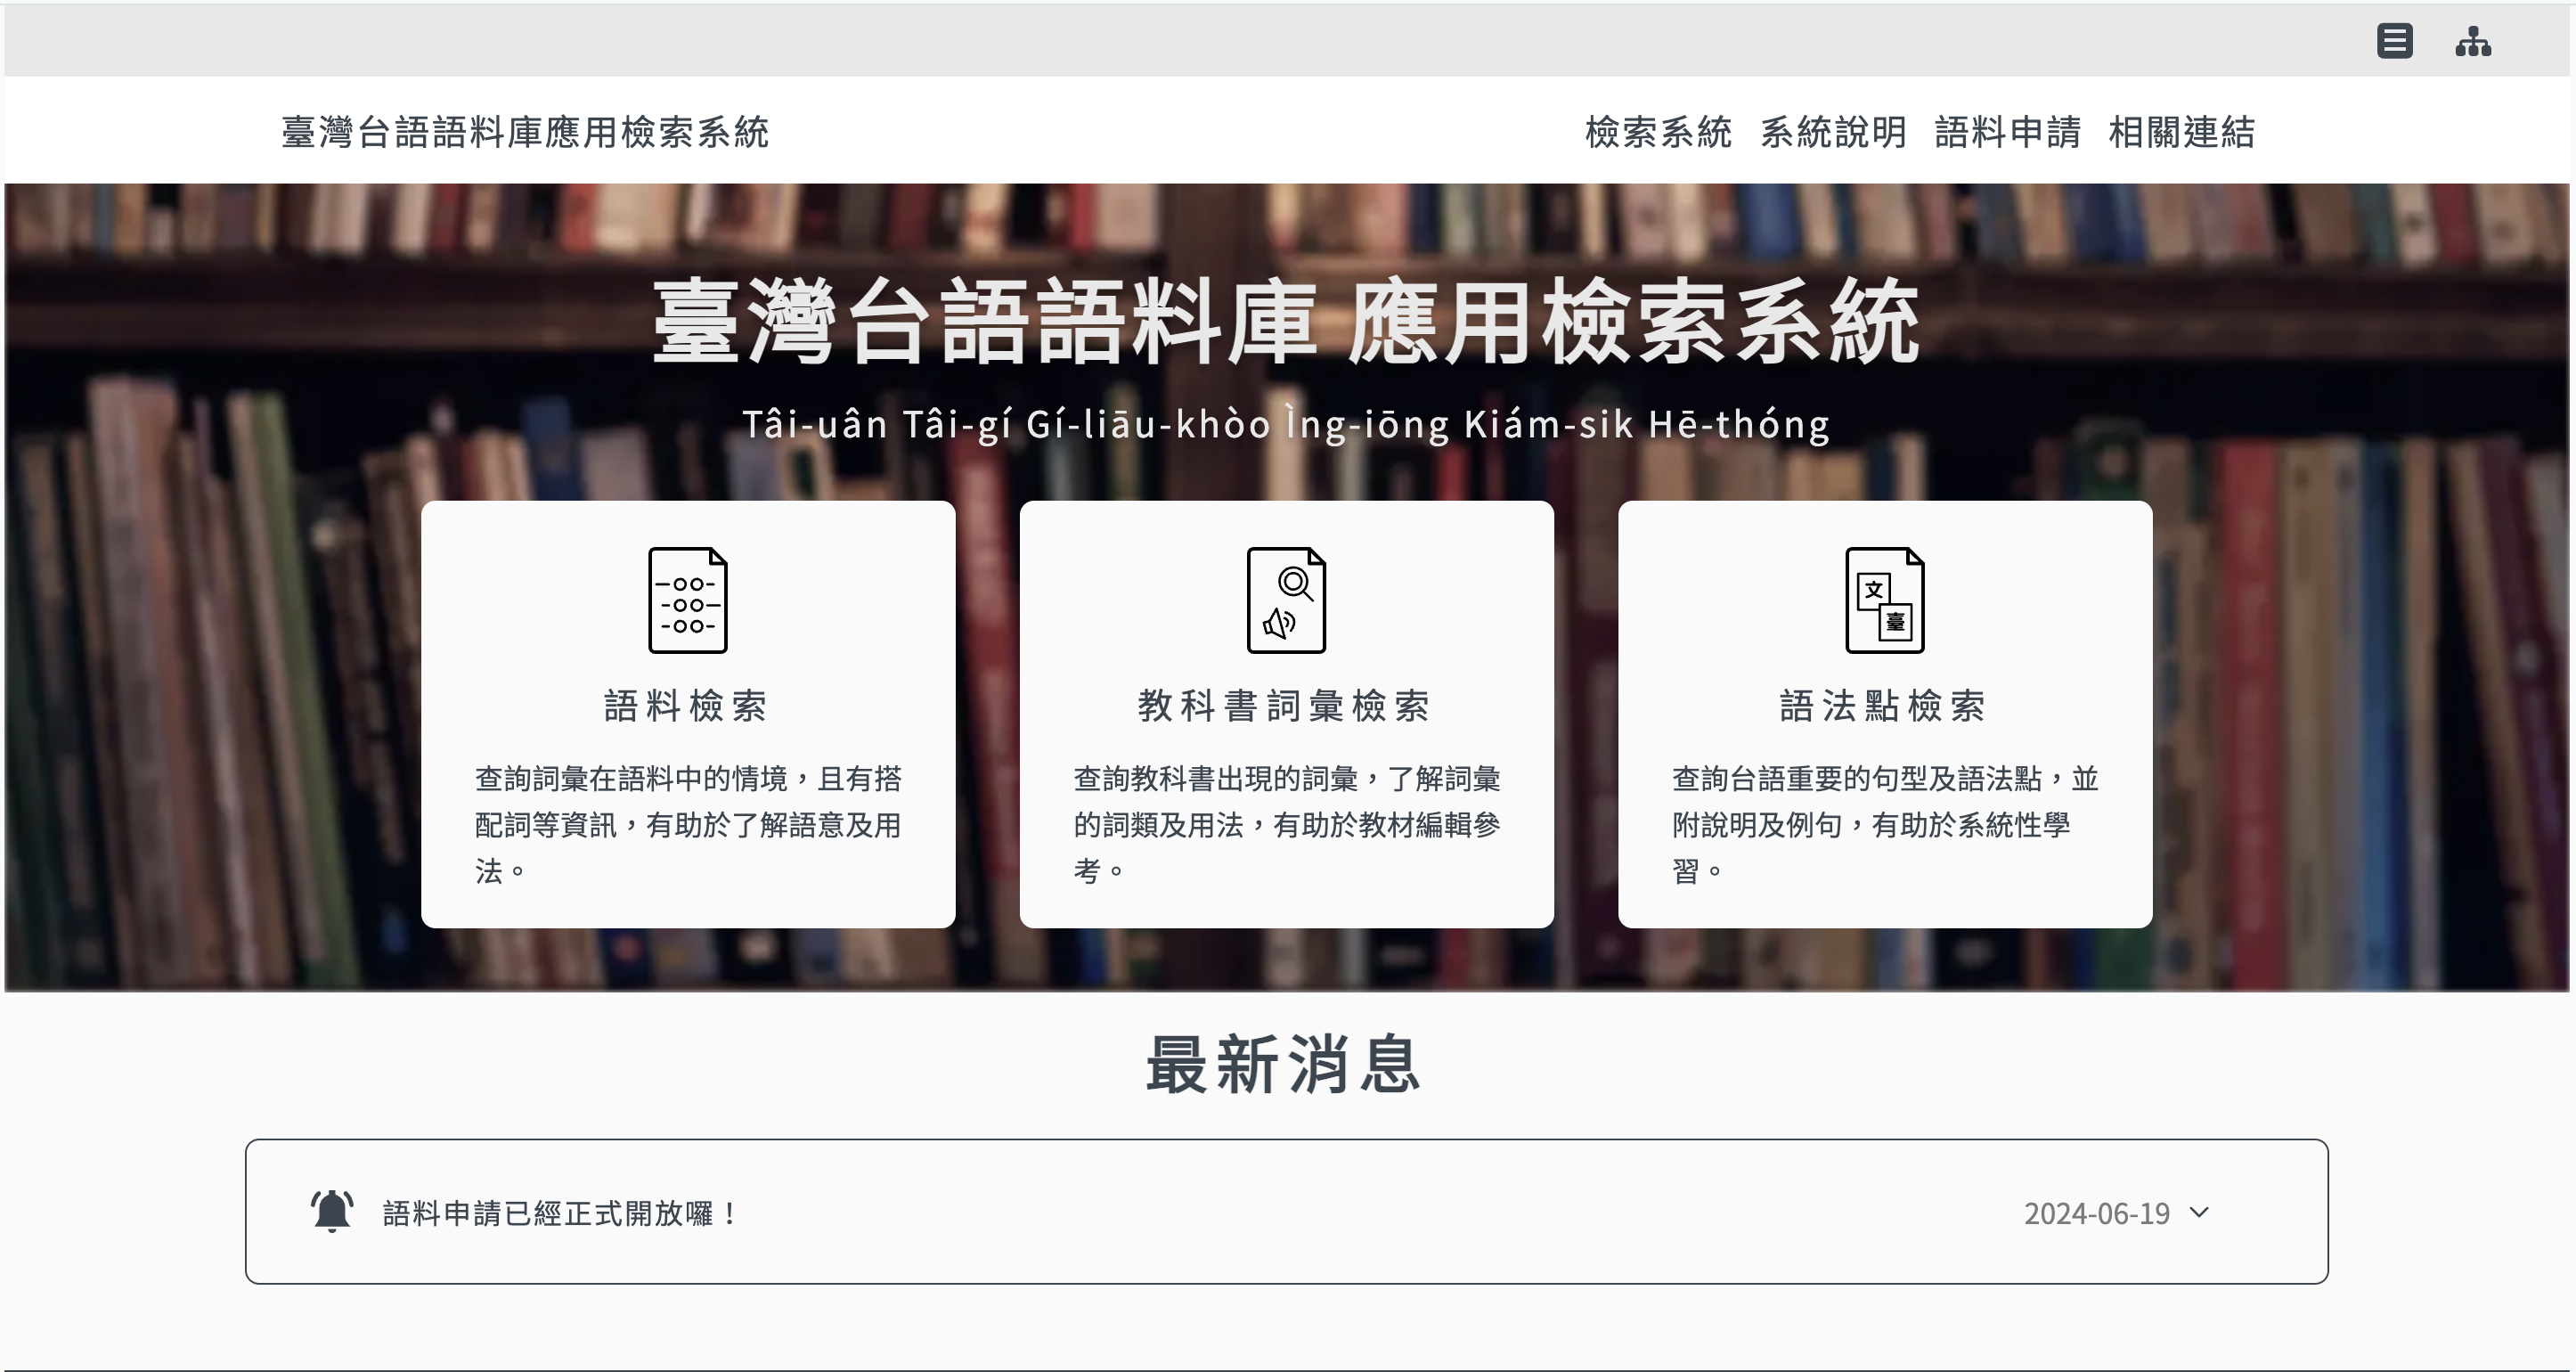
5xRuby brought together corpus import, automatic word segmentation, romanization matching, multi-dimensional search, and user requests and feedback.
Because of the characteristics of Taiwanese, validating the segmentation of a single corpus entry takes nearly ten cleaning rules, cross-checking punctuation, hyphens, tone marks, and spacing, to ensure the resulting Han character array and Tâi-lô array align perfectly.
The system integrates eight dictionary databases (including a Mandarin–Taiwanese dictionary, a practical Taiwanese dictionary, textbook vocabulary, grammar points, and difficult sentence references) and offers numeric tone search: users simply type a number from 1 to 8, and the system converts it to the corresponding tone mark for matching.
The system also provides complete user services, including corpus request workflows, error reporting, and feedback, so researchers and educators can easily access this valuable language data.
Core Strengths
End-to-end system integration: Corpus import, automatic segmentation, romanization matching, multi-dimensional search, and user request and feedback mechanisms are connected into a one-stop national language database platform.
Proprietary segmentation and romanization matching: Overcoming the complexities of Taiwanese, the system automatically segments long sentences while applying ten cleaning rules for punctuation, hyphens, tone marks, and spacing, keeping the Han character and Tâi-lô arrays fully aligned.
Cross-database integration and numeric tone search: Eight dictionary databases, including Mandarin–Taiwanese, practical Taiwanese, and textbook vocabulary, are integrated with a numeric tone search feature. Users can enter codes 1–8 to find Taiwanese entries by tone, solving the challenge of searching characters with multiple readings and tones and providing a smooth experience for academic and practical queries.
Reliable large-scale database architecture: Built to hold the extensive corpus assets of a national research institution, the database system is highly scalable and rigorously secured, demonstrating strong algorithm development and data processing capabilities.
Comprehensive researcher services: Standardized corpus request workflows, error reporting, and feedback mechanisms make it much easier for researchers and educators to access these valuable language assets.